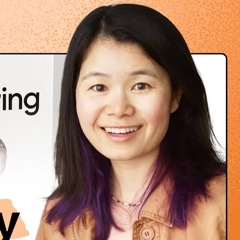
Chip Huyen
Core developer on Nvidia's NeMo platform, former Netflix AI researcher, Stanford ML instructor, two-time founder, author of AI Engineering
Where to hear and read about Chip Huyen1 episode or test

Chip Huyen is a core developer on Nvidia's NeMo platform, a former Netflix AI researcher, a Stanford ML instructor, a two-time founder and the author of AI Engineering. The most useful thing to learn from her is that AI apps improve far more from knowing users, preparing data and fixing workflows than from chasing new models, frameworks or vector databases.
You don't have to be like absolutely perfect at things to win. You just need to be like good enough and being consistent about it.
Al Engineering 101 with Chip Huyen (Nvidia, Stanford, Netflix)
Chip Huyen: the story and the lessons
1What Chip Huyen says actually improves an AI app
Huyen says most teams fuss over news and tooling, not users and data. Her viral LinkedIn post set popular beliefs against what works. The popular list: follow AI news, adopt the newest agentic framework, agonize over vector databases, rank which model is smarter, fine-tune.
Her list of what works: talk to users, build more reliable platforms, prepare better data, optimize end-to-end workflows and write better prompts. She says it hit a nerve because the first list is what people keep asking her about.
She tells teams to read user feedback instead of following every headline. When people ask her to choose between technologies such as MCP and agent protocols, she points them to what users want and don't want. She says feedback improves an app "way way way more" than following the news.
Huyen asks two questions before adopting any new tool or protocol. First, how much better is the optimal choice than a non-optimal one, which she says is often not much. Second, how hard would it be to switch it out later.
She warns against overcommitting to a technology that has not been battle tested, because an untested choice you cannot swap leaves you stuck.
She sees an idea crisis: capable tools but teams stuck on what to build. AI can draft a design, write code and build a website, yet at company hackathons many people don't know what to build. Most companies try the tools, see little and stop.
She links it to specialization, since people focus on one thing and lack the big picture that ideas need. She does not pick between top-down and bottom-up strategy and says a mix works.
Huyen finds project ideas by logging a week of frustrations. She suggests noting what frustrates you at work, asking if it could be done differently, and swapping notes with teammates to find shared pain.
She is bullish on micro tools that make life a bit easier. Lenny's app that downloads every image from a Google Doc URL is her example.
2How Chip Huyen approaches RAG and data preparation
She says RAG quality comes from data preparation, not the database. In the companies she has seen, the biggest performance gains in RAG came from better data preparation. Database choice still matters for latency and for read-heavy or write-heavy access, but it does not decide answer quality.
She dates the idea of RAG to a 2017 question-answering paper that retrieved Wikipedia text for each question and put it in the context.
Huyen attaches summaries, metadata and hypothetical questions to each chunk. Long documents get split, so a later chunk can lose the key term, such as the name of the person the document is about. A query for that name then never finds it.
Chunk size is a trade-off. Long chunks carry more metadata but fit fewer in the context, while short chunks reach more documents but may be too small to hold the answer. With hypothetical questions, a query is matched against the questions each chunk could answer.
She rewrites source content into question and answer pairs. Instead of chunking a podcast transcript raw, one team used AI to rewrite it as many questions with answers, so user questions match answers directly.
She heard from that team that the change gave a very big performance gain.
Huyen says documentation needs an extra layer before an AI can use it. Docs written for humans assume common sense a model lacks. One team added an annotation layer that says what a temperature output of 1 means on a scale from -1 to 1.
The model reads the number but cannot guess the scale unless it is written down. The team reported a big change from the layer.
3Chip Huyen on evals
She treats evals as a return-on-investment decision, not a rule. Two engineers on evals might lift a working feature from 80% to 85%, while a new feature could add far more. She goes strict on evals at scale, where failures are catastrophic, or where the feature is a competitive edge.
She says skipping evals is not her own philosophy, since she loves writing them. But she has watched strong teams go on vibes when traffic rises and customers seem happy, at the cost of blindness to dumb or expensive behavior.
Huyen evaluates every step of a multi-step pipeline, not only the output. For a deep research tool, she checks the search queries first, since five near-identical queries add nothing. Then she checks results for overlap, breadth, depth and relevance to the original prompt.
Judging only the final report is costly and slow and does not show where things break. A benchmark where 100 experts write prompts and review answers is an example of that cost.
She uses evals to find weak user segments. One review of a poorly served user segment found the real problem was weak messaging, not the model.
Some products carry hundreds of metrics, such as verbosity, sensitive data and length. Her advice is to focus on things you can improve significantly.
Huyen argues evals are a system problem that pulls teams together. Evals need component architecture, user behavior knowledge and guardrails, so product, engineering and user acquisition must communicate more.
She notes her sample is biased toward forward-looking executives, and that organizations are moving faster than she expected.
4What Chip Huyen sees inside companies adopting AI
She finds customer-facing AI gets adopted because its outcome is measurable. Booking and sales chatbots are popular because conversion with and without the bot is easy to compare. Internal tools such as coding assistants and HR bots stall because the payoff is hard to see.
Many companies buy ChatGPT and Claude Code subscriptions and run upskilling workshops, then see low usage and ask what is wrong. She says a company's AI strategy rests on use cases and talent.
Huyen says nobody can measure AI productivity, so people go on feel. Asked if coding agents help, people say they feel better, citing more PRs and more code. She calls lines of code a poor metric.
She doubts that no one is more productive. Her view is that the measurement problem, not a lack of benefit, is the main obstacle.
Managers pick headcount over AI tools, while VPs pick the tools. Offered costly coding-agent subscriptions or one extra headcount, almost all managers take the headcount. VPs who run many teams tend to take the tools.
She says managers still growing a team gain a lot from one more person, and the reason is size, not productivity. Executives watch business metrics, so she advises defining which metrics matter first.
A friend's company ran a bucketed trial of Cursor across 30 to 40 engineers. The manager split the team into best, average and lowest performers without telling them, and gave half of each group Cursor. The top group gained most, then the average group.
Another company found senior engineers the most resistant, saying AI-generated code just sucks. Chip says she has not reconciled the two reports, and that she does not know the mechanics of the trial.
She sees companies pairing junior code generation with senior review. Two companies told her they have juniors write code while seniors write guidelines and spend more time on PR review, preparing to need only a few very strong engineers.
The open question she raises is how anyone becomes a strong senior if juniors aren't hired. The counterargument is that curious AI-native juniors could grow fast.
Huyen's own debugging story shows why system thinking lasts. Claude Code kept changing variables, functions and languages on a hosting bug. The real cause was that her plan tier lacked the feature, which she found by reading the docs herself.
She says AI does well on clear, well-defined tasks and poorly where many components interact. Citing Stanford's Mehran Sahami, she notes that coding is a means to an end and the problems just get bigger.
5How Chip Huyen explains model improvement
She says big gains now come from post-training, not bigger base models. Pre-training has used up the available text data, and labs have very similar pre-training data. Whether GPT-5 was a jump on the scale of GPT-2 to 3 to 4 is debatable, in her view.
She tried raw pre-trained models through friends who train them and found them "horrendous". Users only ever meet models after post-training.
Huyen calls sampling strategy an underrated, cheap lever. A model produces a distribution over next tokens, and the sampling choice decides between always taking the likeliest token or something more creative.
She says the right choice can boost performance "in a huge way".
She notes extra inference compute can make the same model look much better. Test time compute can mean generating several answers and picking the one most agree on, such as three of four saying 42. It can also mean letting the model produce more thinking tokens before it answers.
The base model is unchanged, but users see a stronger result. She says labs keep debating how to split compute among pre-training, post-training and inference.
Huyen treats voice AI as a latency and interruption problem. Voice chains speech to text, a text answer and text to speech, so latency matters a lot. The hard part is telling a real interruption from a listener's "mhm".
She calls interruption detection a classic classifier problem, so it is more an engineering challenge than a foundation-model one. Possible rules may require disclosing that the user is talking to an AI.

Al Engineering 101 with Chip Huyen (Nvidia, Stanford, Netflix)
Chip Huyen explains pre-training, post-training, RL, evals and RAG in plain terms, then shares what she sees inside enterprises building AI products. The worth-hearing result: better data preparation, user feedback and system thinking improve AI apps far more than chasing new models, frameworks or vector databases.
Huyen says most teams fuss over news and tooling, not users and data. Her viral LinkedIn post set popular beliefs against what works. The popular list: follow AI news, adopt the newest agentic framework, agonize over vector databases, rank which model is smarter, fine-tune.
Her list of what works: talk to users, build more reliable platforms, prepare better data, optimize end-to-end workflows and write better prompts. She says it hit a nerve because the first list is what people keep asking her about.
She tells teams to read user feedback instead of following every headline. When people ask her to choose between technologies such as MCP and agent protocols, she points them to what users want and don't want. She says feedback improves an app "way way way more" than following the news.
Huyen asks two questions before adopting any new tool or protocol. First, how much better is the optimal choice than a non-optimal one, which she says is often not much. Second, how hard would it be to switch it out later.
She warns against overcommitting to a technology that has not been battle tested, because an untested choice you cannot swap leaves you stuck.
She sees an idea crisis: capable tools but teams stuck on what to build. AI can draft a design, write code and build a website, yet at company hackathons many people don't know what to build. Most companies try the tools, see little and stop.
She links it to specialization, since people focus on one thing and lack the big picture that ideas need. She does not pick between top-down and bottom-up strategy and says a mix works.
Huyen finds project ideas by logging a week of frustrations. She suggests noting what frustrates you at work, asking if it could be done differently, and swapping notes with teammates to find shared pain.
She is bullish on micro tools that make life a bit easier. Lenny's app that downloads every image from a Google Doc URL is her example.
She says RAG quality comes from data preparation, not the database. In the companies she has seen, the biggest performance gains in RAG came from better data preparation. Database choice still matters for latency and for read-heavy or write-heavy access, but it does not decide answer quality.
She dates the idea of RAG to a 2017 question-answering paper that retrieved Wikipedia text for each question and put it in the context.
Huyen attaches summaries, metadata and hypothetical questions to each chunk. Long documents get split, so a later chunk can lose the key term, such as the name of the person the document is about. A query for that name then never finds it.
Chunk size is a trade-off. Long chunks carry more metadata but fit fewer in the context, while short chunks reach more documents but may be too small to hold the answer. With hypothetical questions, a query is matched against the questions each chunk could answer.
She rewrites source content into question and answer pairs. Instead of chunking a podcast transcript raw, one team used AI to rewrite it as many questions with answers, so user questions match answers directly.
She heard from that team that the change gave a very big performance gain.
Huyen says documentation needs an extra layer before an AI can use it. Docs written for humans assume common sense a model lacks. One team added an annotation layer that says what a temperature output of 1 means on a scale from -1 to 1.
The model reads the number but cannot guess the scale unless it is written down. The team reported a big change from the layer.
She treats evals as a return-on-investment decision, not a rule. Two engineers on evals might lift a working feature from 80% to 85%, while a new feature could add far more. She goes strict on evals at scale, where failures are catastrophic, or where the feature is a competitive edge.
She says skipping evals is not her own philosophy, since she loves writing them. But she has watched strong teams go on vibes when traffic rises and customers seem happy, at the cost of blindness to dumb or expensive behavior.
Huyen evaluates every step of a multi-step pipeline, not only the output. For a deep research tool, she checks the search queries first, since five near-identical queries add nothing. Then she checks results for overlap, breadth, depth and relevance to the original prompt.
Judging only the final report is costly and slow and does not show where things break. A benchmark where 100 experts write prompts and review answers is an example of that cost.
She uses evals to find weak user segments. One review of a poorly served user segment found the real problem was weak messaging, not the model.
Some products carry hundreds of metrics, such as verbosity, sensitive data and length. Her advice is to focus on things you can improve significantly.
Huyen argues evals are a system problem that pulls teams together. Evals need component architecture, user behavior knowledge and guardrails, so product, engineering and user acquisition must communicate more.
She notes her sample is biased toward forward-looking executives, and that organizations are moving faster than she expected.
She finds customer-facing AI gets adopted because its outcome is measurable. Booking and sales chatbots are popular because conversion with and without the bot is easy to compare. Internal tools such as coding assistants and HR bots stall because the payoff is hard to see.
Many companies buy ChatGPT and Claude Code subscriptions and run upskilling workshops, then see low usage and ask what is wrong. She says a company's AI strategy rests on use cases and talent.
Huyen says nobody can measure AI productivity, so people go on feel. Asked if coding agents help, people say they feel better, citing more PRs and more code. She calls lines of code a poor metric.
She doubts that no one is more productive. Her view is that the measurement problem, not a lack of benefit, is the main obstacle.
Managers pick headcount over AI tools, while VPs pick the tools. Offered costly coding-agent subscriptions or one extra headcount, almost all managers take the headcount. VPs who run many teams tend to take the tools.
She says managers still growing a team gain a lot from one more person, and the reason is size, not productivity. Executives watch business metrics, so she advises defining which metrics matter first.
A friend's company ran a bucketed trial of Cursor across 30 to 40 engineers. The manager split the team into best, average and lowest performers without telling them, and gave half of each group Cursor. The top group gained most, then the average group.
Another company found senior engineers the most resistant, saying AI-generated code just sucks. Chip says she has not reconciled the two reports, and that she does not know the mechanics of the trial.
She sees companies pairing junior code generation with senior review. Two companies told her they have juniors write code while seniors write guidelines and spend more time on PR review, preparing to need only a few very strong engineers.
The open question she raises is how anyone becomes a strong senior if juniors aren't hired. The counterargument is that curious AI-native juniors could grow fast.
Huyen's own debugging story shows why system thinking lasts. Claude Code kept changing variables, functions and languages on a hosting bug. The real cause was that her plan tier lacked the feature, which she found by reading the docs herself.
She says AI does well on clear, well-defined tasks and poorly where many components interact. Citing Stanford's Mehran Sahami, she notes that coding is a means to an end and the problems just get bigger.
She says big gains now come from post-training, not bigger base models. Pre-training has used up the available text data, and labs have very similar pre-training data. Whether GPT-5 was a jump on the scale of GPT-2 to 3 to 4 is debatable, in her view.
She tried raw pre-trained models through friends who train them and found them "horrendous". Users only ever meet models after post-training.
Huyen calls sampling strategy an underrated, cheap lever. A model produces a distribution over next tokens, and the sampling choice decides between always taking the likeliest token or something more creative.
She says the right choice can boost performance "in a huge way".
She notes extra inference compute can make the same model look much better. Test time compute can mean generating several answers and picking the one most agree on, such as three of four saying 42. It can also mean letting the model produce more thinking tokens before it answers.
The base model is unchanged, but users see a stronger result. She says labs keep debating how to split compute among pre-training, post-training and inference.
Huyen treats voice AI as a latency and interruption problem. Voice chains speech to text, a text answer and text to speech, so latency matters a lot. The hard part is telling a real interruption from a listener's "mhm".
She calls interruption detection a classic classifier problem, so it is more an engineering challenge than a foundation-model one. Possible rules may require disclosing that the user is talking to an AI.