In the Bible story, the builders lose their shared language and the tower is never finished. Bruegel painted it already leaning, with layers that don't line up.
It is the risk of building big with many hands. Agents give you the hands. These principles are how to start their work, check it, teach them, and aim them high, without the tower leaning.
Practical principles for building with agents
We built Oncourse AI to 80k+ signups as a small, bootstrapped team, and built Caddie on the side. Neither would have been possible working the way most teams still work. These principles are how we did it.
Harsha Garlapati, Shubhdeep Srivastava and Prasad Kompalli ·  Oncourse AI · October 2026
Agents now write most of the code, so the slow part is your attention. These are the principles to spend it well.
Most teams still plan as if writing code were the slow part. Agents now write most of the code, so the slow part is the attention of the person in charge.
That shift is how a small, bootstrapped team runs Oncourse AI, and how one person can build a second product on the side. Caddie took 730 commits in 15 days, working alone with agents. Neither would have happened working the way most teams still do.
Agents leave you three jobs: starting work, checking it, and teaching them what good looks like. The principles are grouped by those jobs. The last one is about what to aim at once the three are running.
Start every task the second you know about it
TodayTasks go into a backlog and wait to be picked up.InsteadGive each task to an agent the second it is written down.
Spend your time on triage and context, not on the task
TodayYou write a one-line ticket and explain it later, in standups and threads.InsteadDecide what matters, then start each agent with the context it needs: who asked, why, and what done looks like.
Plan delivery dates, not start dates
TodaySprint planning decides what starts this week and what waits for the next one.InsteadKeep the dates customers rely on, and start every planned task today.
Keep at least five agents running, day and night
TodayMost people run one agent and watch it work.InsteadKeep five or more running every hour, including while you sleep.
Give each project a coordinator agent
TodayYou hand out every task and chase every thread yourself.InsteadGive each project a coordinator that watches its Slack channels, hands work to the right agent, and brings back one summary.
De-risk the merge button
TodayCode review means reading every line before you press merge.InsteadMake merging safe: confirm every finding in the code, and let tests and the build check every line.
Audit the app with personas, not checklists
TodayQA runs a checklist for each feature.InsteadKeep a shared library of personas built from real customers, and have agents test each feature as a different set of them.
Set up Kaizen routines that improve the work every day
TodaySmall improvements wait for a polish sprint that rarely comes.InsteadSet up routines where agents improve the work every day, in small steps or large ones, and check that earlier fixes held.
Let production problems open their own pull requests
TodayErrors and slow endpoints sit on a dashboard until someone has time to look.InsteadPoint agents at your monitoring, so an error or a slow endpoint opens a fix on its own.
Turn every good result into a skill
TodayYou make one good post, video or fix, and move on.InsteadWhen an experiment works, turn how you made it into a skill, so agents can repeat that quality again and again.
Give every skill its references and the recipe behind them
TodayA skill is a saved prompt, or a few good examples with nothing saying why they work.InsteadKeep the reference examples that set the bar, add the steps and reasons that made them work, and test the skill on a fresh agent.
Read your agents' traces every week
TodayAn agent's run disappears once the task is done.InsteadSend every agent call through one AI proxy, review the traces weekly, and turn what you find into skills.
Give your agents MAD goals: measurable, absurd and daily
TodayRoadmaps are sized for what a few people can do in a quarter.InsteadGive agents goals a team of people would never attempt, like "make the app 10x faster."
Take ideas from three sources, not from the roadmap
TodayIdeas come from the roadmap and from what the team finds interesting, and you learn whether anyone wants one after it ships.InsteadPick ideas that pull in a demo, meet a real need, or come from your own conviction. Build the ones that do all three first, and the rest for the fun of it.
Prototype live with agents, not in the background
TodayYou hand an idea to an agent, switch to something else, and come back an hour later to one attempt.InsteadSit with the agent: ask for ten approaches, ten versions of the best one, react to each, and iterate in minutes.
Start every task the second you know about it
Give each task to an agent the second it is written down.
Follow one task from the day someone writes it down to the day it ships. In a typical team that plans in sprints, the work takes a day and the task takes two weeks. It waits in the backlog, then for planning, then for someone to be free.
An agent should make a first version in minutes. When the work takes minutes, the days a task spends waiting in a queue become almost all of its time. So start every task the second you know about it, even one that won't ship for weeks.
A one-day task spends most of its two weeks waiting to start
The same task, from the day it's written down to the day it ships, in working days.
A meeting should start work, not add tasks
Meetings are where most tasks start. A typical call ends with a list of action items, and each one becomes another task in the queue. A meeting shouldn't add tasks. It should start the work. In Caddie, when a call ends, its Get it done card drafts each follow-up and hands it to an agent: the email, the Slack message, the PRD, even the payment. Anything sent in your name waits for your OK, and nothing lands on your to-do list.
A call should end with every follow-up already drafted
Caddie's Get it done card. Open one to see the draft, then send it, or Do all.
As promised, here's the pricing for 40 seats. The annual plan saves you two months, and onboarding is included.
Happy to walk your team through it on Thursday.
Onboarding mockups from today's call with Kestrel 👇 Maya liked option B. Can we tighten the empty state before Thursday?
Problem
Teams export one note at a time. Kestrel's ops lead needs 500 notes for an audit.
Done when
500 notes export as Markdown in under a minute, with their folders.
The same rule applies to bugs. On the night of 22 October, an audit found that a deleted call note could come back after a workspace switch. An agent fixed it that night, and the fix shipped in version 0.5.48.
Measure time to happy, not time to close
 Minute 0Ravi reports export is broken
- Minute 1An agent turns Ravi into a persona
- Minute 3Another agent fixes the export
- Minute 4The persona tries the fix as Ravi
- 😊Minute 5Ravi gets a reply, and it works
Measure time to happy: the minutes from a customer raising a problem to that customer being happy with the fix. Aim for five minutes. An agent fixes the problem, and a persona agent built from that customer checks the fix before anyone replies.
Support teams measure time to resolution, the hours from a ticket being opened to it being closed. Engineering teams measure cycle time. Both stop the clock when the team marks the work done, and the customer may still be stuck.
Measure something else instead: time to happy. The clock starts when a customer raises a problem, in a user interview, an email or a bug report. It stops when that customer is happy with the fix. Aim for five minutes.
A person can't fix and check a bug in five minutes, but agents working together can. One agent turns the customer into a persona: who they are, their device, and what they were trying to do. Another agent fixes the problem. Then the persona agent walks through the fix as that customer before anyone replies. If the persona wouldn't be happy, the fix isn't done.
The same goes for planned work. Say on Monday you plan an export feature that is due in three weeks. An agent drafts it that afternoon. The draft shows the hard part is the file format, not the screen, so the plan changes on day one instead of in week three.
Spend your time on triage and context, not on the task
Decide what matters, then start each agent with the context it needs: who asked, why, and what done looks like.
When agents do the work, your time moves to the two minutes before they start. Those two minutes decide whether the first version ships or gets thrown away.
Spend them on triage first. Is this worth doing at all? How urgent is it? Which agent is set up for it? Most tasks die here, and they should.
Spend two minutes on triage and context, then hand off to the agent already on it
A bug report comes in. You add what an agent can't ask for, and hand it to the agent already working on export.
Then add the context a new teammate would need. Who asked, and what were they trying to do? Link the Slack thread, the call or the customer's email. Say what done looks like, and what the agent must not touch. An agent that starts with the full picture needs one review. An agent that starts with one line needs five.
Plan delivery dates, not start dates
Keep the dates customers rely on, and start every planned task today.
Sprint planning sets two dates for each task: when work starts and when it ships. Start dates exist because a person can only hold a few tasks at once.
Agents don't have that limit. Keep the delivery dates, because customers and teammates rely on them. Drop the start dates. Every task in the weekly plan gets an agent the day it enters the plan.
By the next planning meeting, every task has a draft, a prototype or a failed attempt. The meeting stops estimating work and starts judging it. A failed attempt is useful too, because it shows what the task really needs.
Every task in the plan should start on Monday
The same four tasks. In the new way, each one starts Monday and finishes when it's ready.
In Caddie you hand a task to an agent from your task list, and the planner keeps tasks an agent holds out of your day.
Keep at least five agents running, day and night
Keep five or more running every hour, including while you sleep.
With one agent, you write a prompt and watch it work. You have swapped waiting for a person for waiting for a machine.
With five or more, something is always finished. While one agent works, review what another made. With fewer than five, you end up waiting. The upper limit is how much you can check well, which is principle 2.1.
They shouldn't stop when you do. Before you sleep, start the long jobs, like audits and research. By morning, a night's work should be waiting for review. Many of Caddie's audits ran overnight. The overnight agents run work you can check; discovering what to build happens with you, in principle 4.3.
Agents should keep working while you sleep, so a night's work waits for you in the morning
One day, 6pm to 6pm. Bars are agents working. Dots are you reviewing.
Caddie's Agents inbox lists every agent by who needs you, including Caddie's own agents, T3 Code threads, and Claude Code and Codex sessions. An agent's question reaches you in the Mac's notch or on your iPhone, so no agent sits idle waiting for an answer.
Give each project a coordinator agent
Give each project a coordinator that watches its Slack channels, hands work to the right agent, and brings back one summary.
Five agents running day and night need managing: who works on what, what is stuck, what is done. Do that yourself and you are the bottleneck again.
So give the job to an agent, one per project. Oncourse has its coordinator and Caddie has another, each with its own channels, agents and memory. A coordinator reads each request and hands it to the agent best set up for it. A follow-up goes to the agent already on that topic instead of starting a new one. When the work is back, you get one short summary of what each agent did and what needs you.
Point it at the places requests arrive. It watches Slack continuously, so when a teammate asks for something, the work has started before you read the message. It never sends or posts as you without asking first.
Each project's coordinator should hand out its work, so you read one summary per project
Requests come in from Slack, meetings and email. Agents do the work.
 Slack
 Meetings
 Gmail
In Caddie, every account comes with a Coordinator, and you can make one for each project. Slack messages and meeting follow-ups go to it, and it hands work to your other agents and T3 Code threads.
De-risk the merge button
Make merging safe: confirm every finding in the code, and let tests and the build check every line.
Agents write more code than anyone can read line by line. So spend your reading where it matters most, on what the agents claim.
When an agent reports a bug, confirm it in the code before anyone fixes it. Agents report wrong findings in the same confident tone as right ones, and a fix for a bug that doesn't exist is a new bug.
Say an agent reports that checkout charges tax twice. You open the code and see it was reading an old test file. If another agent had "fixed" it, a working checkout would now be broken.
Let machines check the rest. Tests, type checks and the build run on every change. When several agents finish, confirm each change is still there, because a later agent can quietly undo an earlier one. And decide yourself anything that reaches the outside world, like a default, a permission or a release.
Every finding should pass through a person before an agent fixes it
Real findings go on. Wrong ones stop at you.
Give agents tools to check their own work
Code review bots only read the code. The better check is whether the app works. Give agents a way to see it: screenshots of every screen they changed, compared with what was expected, and computer use to click through the flow like a person would.
Agents should see the app working, not just read the code
Before asking for review, the agent checks its change on a real screen.
- ✓Screenshots match the design
- ✓Signup flow clicked through by computer use
- !Button cut off on a small phone
- ↻Fixed and checked again
An agent that can see its own result fixes most of its mistakes before you look. Your review then starts from working software, not from a diff.
Review the two kinds of pull requests differently
Not all work needs the same review. Some of it you can check with a test. The rest you are still discovering, and only you can judge it.
Hand off the work a test can check, and review the work you are still discovering
- Faster queries and endpoints
- Errors that keep repeating
- Database maintenance
- Kaizen and audit fixes
- New features
- Ideas and prototypes
- Anything users will see differently
Self-healing pull requests fix what already exists. A faster query, a retry on a flaky call, an error that stops repeating. You confirm the problem is real; the checks above confirm the fix works. Then trust the agent and let it merge.
Feature pull requests change what users see. Those still get your review, because they carry decisions about the product that no test can make.
Audit the app with personas, not checklists
Keep a shared library of personas built from real customers, and have agents test each feature as a different set of them.
Think of a call recorded on the Mac, a workspace switch, then the note opened on a phone. No checklist for meetings or for workspaces covers that walk.
So give the audit agents personas. A persona is a specific person with a reason to open the app, a device and settings, permissions they deny, and 8 to 12 steps they take in order, including quitting and reopening. The agents trace the code at each step and ask what this person would see.
Pick different testers for each feature. Before a feature ships, choose the four or five personas it affects most. A new checkout goes to someone on a slow phone and a parent paying for their child. Offline mode goes to someone on a patchy connection and someone with low battery. Add new variations in every audit, so each one tries routes no earlier audit tried. We have used more than 120.
Build personas from real customers, in one shared place
Keep a library of 20 to 30 personas, built from real customers. Build them from what people actually say: user interviews, support emails, and Reddit threads where people describe their problems in their own words.
Then keep them in one shared place, so the whole team and every agent works from the same people. The library grows with research: every interview or support thread either adds a persona or sharpens one. In Caddie, that place is a team workspace.
Keep one shared library of personas, and test each feature with a different set
Each feature gets its own testers from one shared library.
Set up Kaizen routines that improve the work every day
Set up routines where agents improve the work every day, in small steps or large ones, and check that earlier fixes held.
Kaizen is the practice of continuous improvement that Toyota made famous. Many small improvements, made all the time, by the people doing the work. Agents make it cheap enough to do every day.
Set it up as a routine, a scheduled job an agent runs on its own. Each run looks over recent work, improves what it finds, and checks that the last run's fixes held. Point routines at anything that should keep getting better: the product, the onboarding emails, the help docs, the sales deck.
Don't stop at small fixes. Give a routine ambitious goals: find hundreds of bugs, make the app faster, cut its load time in half. Have it test each change from the point of view of hundreds of different personas, such as a student in their first year of study and one in their final year, so every improvement holds for every kind of user.
These fixes are the self-healing kind. They merge once the checks pass, and you read the summary.
The check on earlier fixes is the step people skip. Without it, a fix can quietly break a week later. With it, a fix that breaks is caught the next day.
Re-check yesterday's fixes so small improvements add up
Two weeks of small daily fixes.
In Caddie, Kaizen is the first routine the Routines page suggests, with an agent of its own.
Let production problems open their own pull requests
Point agents at your monitoring, so an error or a slow endpoint opens a fix on its own.
Production problems should start their own fixes, without waiting for you. When monitoring spots an error or a slow endpoint, that alert should hand the task to an agent automatically, before any user reports it.
Connect it to your agents. When an endpoint slows down or an error starts repeating, an agent reads the logs and traces, finds the cause, and opens a pull request. You review it like any other.
These are the self-healing kind of pull request, so they merge once the checks in principle 2.1 pass.
Monitoring should hand problems straight to agents
Each alert becomes a pull request, ready for review.
At Oncourse, Shubhdeep set this up. Latency on many endpoints has come down, one-off errors that used to cause hiccups have mostly gone, and routine database maintenance happens without anyone scheduling it.
Turn every good result into a skill
When an experiment works, turn how you made it into a skill, so agents can repeat that quality again and again.
A skill is a file of instructions an agent reads before a kind of work. It works like a factory. One good skill improves every output that comes after it.
Say one social media video does well. Most teams celebrate and move on. Instead, write down exactly how it was made: the hook, the pacing, the visual style and the sound. Now any agent can make videos of that quality on any topic.
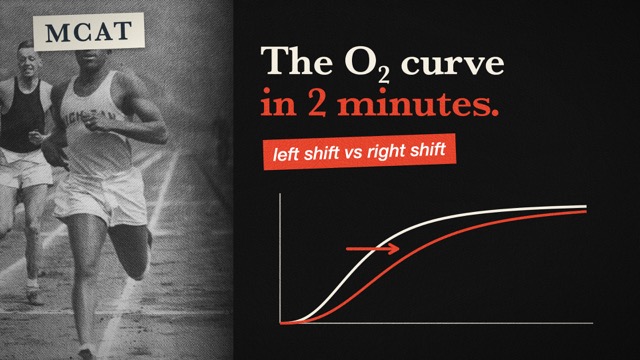
At Oncourse we did this with explainer videos. When one video in the style of Vox worked, we turned the process into a Vox video skill. It covers the paper textures, the type, the 12 frames a second and the documentary sound, so every new video starts at the quality of the best one.
A skill should turn one good result into as many as you need
One explainer that worked, written down as a skill, makes every explainer after it. Play one to see the quality it holds.
 The one that worked
- Hook from a real story
- Paper textures, 12 fps
- Per-letter type
- Documentary sound
Do the same with feedback. If you correct an agent in chat, only that agent learns it. Add the correction to the skill instead, and every agent after it gets it right the first time.
In Caddie, an agent can write a skill itself once it has done a job well, so you don't have to start from a blank page.
Give every skill its references and the recipe behind them
Keep the reference examples that set the bar, add the steps and reasons that made them work, and test the skill on a fresh agent.
Start from references. The result you liked, and the work you admire from others, show an agent the bar better than any description. Keep them in the skill. Then add the recipe on top: how that result was made and why it worked. The Vox video skill links its best videos, and also says to start from a real story, put one idea in each sentence and one picture behind each sentence, and check every frame before rendering.
Then test it the way you'd test code. Give the skill to a fresh agent with no other context and a new topic. If the result isn't as good as the original, the skill is missing a step. Find it and write it down.
Five things make a skill hold up.
- References. The examples that set the bar, yours and others', with a line on what each one gets right.
- Steps in order. The process, from first decision to final check, so an agent can't skip to the end.
- The reason for each step. An agent that knows why a rule exists applies it to cases the rule never named.
- A lessons log. Every critique you give, dated, newest first. The skill gets better every time something goes wrong.
- Pointers, not copies. Link the style guide and the template rather than pasting them in, so the skill never goes stale.
Put the checks in the skill too. Add the lint rules, the automated tests and the workflow that runs them, so every agent that uses the skill also proves its own work.
Keep one skill per kind of work: one for explainer videos, one for blog writing, one for audits. A skill that tries to cover everything gets vague, and vague instructions get average results.
Caddie's agents can save a skill themselves once they've learned a job, and every agent reads your skills before it starts.
Read your agents' traces every week
Send every agent call through one AI proxy, review the traces weekly, and turn what you find into skills.
Route every agent call through one AI proxy and keep the traces. They show where agents got stuck, guessed, or took ten steps for a two-step job.
Read them once a week. Each pattern becomes a line in a skill, or a new skill, so next week's agents skip that detour.
This is principle 3.1 done on purpose. Instead of waiting to notice a bad result, the traces show you every one.
Give your agents MAD goals: measurable, absurd and daily
Give agents goals a team of people would never attempt, like "make the app 10x faster."
Sooner or later you'll ask what the agents should do next. If you can't answer, your goals are too small.
So make every goal MAD. Measurable, so an agent can tell when it has won. Absurd, so a team of people would never try it. Daily, so agents take a fresh run at it every night. "Make the app 10x faster" is MAD. "Improve performance" is not.
Your roadmap was sized for what a few people could do in a quarter. You now have more workers than ideas. So set goals a team of people would never attempt. Make it ten times faster. Make it ten times more accurate.
Give each goal a number an agent can measure, like seconds or error rate. Then agents can try ten approaches overnight, and you only check the attempts that beat the number, and confirm that they really did. Most nights none do. The night one does can change what your product is.
Take learning, the field we care about most. We haven't done this yet, but it is where we'd point every spare agent.
- Make answers more accurate.
- Find better ways to track how a student is progressing.
- Calibrate score predictions, so a predicted 70% means 70% on the day.
- Build synthetic students, so every new method is tested daily before a real student sees it.
- With enough resources, read the research on brain stimulation for learning and design experiments from it.
None of these can ever be finished, so the agents never run out of work.
Take ideas from three sources, not from the roadmap
Pick ideas that pull in a demo, meet a real need, or come from your own conviction. Build the ones that do all three first, and the rest for the fun of it.
When building is cheap, choosing what to build is the whole game. Good ideas come from three places, and each answers a different question.
Build where demand, need and conviction overlap first, then build the edges too
Three places ideas come from, and the question each one answers.
- Demand: does the demo pull?
- Need: what job does it do?
- Conviction: what should exist?
- All three: build these first
- Building is cheap, so build the rest too, for the fun of it.
Demand: does the demo pull? Build around what can be shown well. Make the 15-second video before the feature and post it where your users already are, on TikTok, Instagram or YouTube Shorts. Saves, comments asking where to get it, and waitlist sign-ups are the signal.
Need: what job does it do? Talk to the people you're building for, with a prototype in the room. Don't ask what they want. Show them something an agent built that morning, watch where they get stuck, and change it while they're still on the call.
Conviction: what should exist? Some ideas nobody asks for and no test can prove yet. If you believe the world should have it, build it anyway, and let demand and need shape it rather than decide it.
Read demand as action, not views. A video with fewer views and many comments asking how to get it beats a viral one nobody acts on. The words people use in those comments become the feature's name and its onboarding.
Treat user research as live iteration, the same way as principle 4.3. Agents make a working prototype faster than you can schedule the call, so every interview can test a real thing instead of a question. By the end of a week of calls the prototype has been changed by everyone who used it.
Each source alone can mislead. Demand without need is a fad. Need without demand is a product nobody hears about. Conviction without either is a bet. Build where all three meet first. But building is cheap now, so build the edges too, for the fun of it. Some of the best ideas start as a toy only you believed in. The next post in this series covers the first one in full: working backwards from distribution.
Prototype live with agents, not in the background
Sit with the agent: ask for ten approaches, ten versions of the best one, react to each, and iterate in minutes.
Background agents are for work you can check. Discovering an idea is the other kind of work: there is nothing to check it against yet. Exploring should be a conversation, and you can't have a conversation with someone who answers once an hour.
So when you're shaping an idea, stay in the loop. Ask for ten different approaches side by side. Pick the one that's closest, and ask for ten versions of it. React to each in a sentence, and go again. Three rounds take half an hour and get further than a week of handing work off.
When you're exploring, ask for many versions and react to each one
Three rounds with an agent, in one sitting. Each round starts from the one you picked.
These are the habits that make live iteration work. They come from how we actually work with agents.
- Ask for options, never one answer. Two motions to compare, ten layouts, four titles. You can't judge one version, but you can always pick between two.
- Look at the real thing every round. Open it in the browser, on the phone, at full size. A description of a design hides what a screenshot shows.
- React fast and specifically. "Too much text", "the label looks wrong", "this doesn't say anything". Point at the exact part, ideally with a screenshot.
- Say why. "Too much text, I want to understand it at a glance" teaches the agent your taste. "Change it" teaches nothing.
- Keep what works and change one thing. Each round starts from the version you picked, so good parts don't get lost.
When a round lands, write down why it worked as a skill (principle 3.2). When the direction is settled, hand the build to agents in the background and go back to running five of them.
There are enough problems in the world to be solved. It's time we were ambitious enough to take them on.
Run your agents from the same place as your work
Caddie puts your agents, their questions and your routines next to your notes, tasks and calendar. It uses the Claude Code or Codex you already pay for.